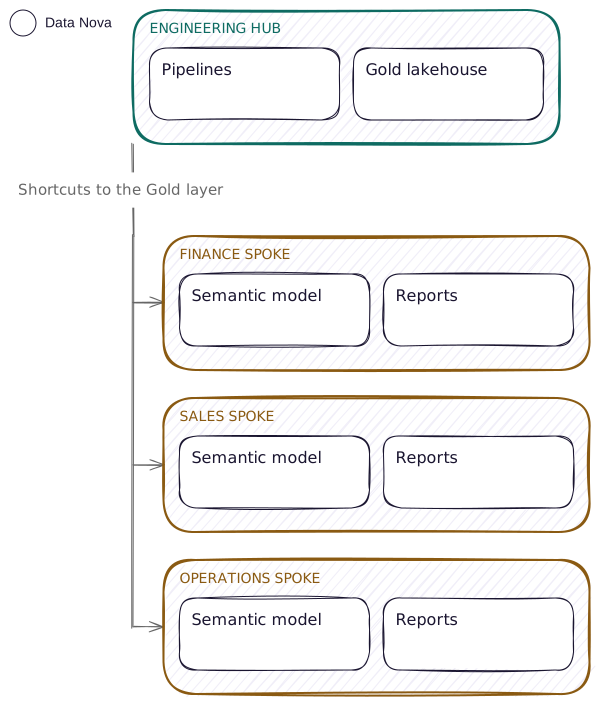
One data engineering workspace acts as the hub, containing all pipelines, lakehouses, and transformation logic. Multiple data analytics workspaces connect to it as spokes, each serving a different consuming team. Each spoke accesses the hub's Gold layer through shortcuts and builds its own semantic models and reports.
Why teams move here
This scales the Split model to support multiple consumers without duplicating the engineering layer. The platform team owns the hub; consuming teams own their spokes, each with its own access controls, capacity allocation, and deployment cycle. The trade-off is coordination: more workspaces mean more shortcuts to manage, more cross-workspace dependencies to track, and more communication between hub and spoke teams.
Pros and cons
Pros
- Single source of truth. All curated data lives in one place, so consuming teams work from the same Gold layer.
- Team autonomy. Each spoke builds, iterates, and deploys without waiting on the platform team.
- Granular access control. Finance sees Finance reports, Marketing sees Marketing reports, and no one stumbles into another team's work in progress.
- Independent capacity and billing. Allocate more capacity to priority teams, or charge back costs by department.
- Scales horizontally. A new consuming team means a new spoke and a shortcut. The hub doesn't change.
Cons
- Shortcut proliferation. Every spoke needs shortcuts to the hub, and the number to create, maintain, and audit grows with each one.
- Hub becomes a bottleneck. If the platform team is slow to deliver tables or fix data quality, every spoke is blocked.
- Limited cross-spoke visibility. Two teams needing to share assets or collaborate first have to figure out where something lives and who owns it.
- Coordination overhead. A schema change in the hub can break multiple downstream workspaces at once.
- Growing governance complexity. More workspaces mean more to audit, more capacity to monitor, and more deployment pipelines to manage.
Where this fits
- Central BI platform serving multiple business units. A platform team owns engineering; Finance, Marketing, Operations, and Sales each have their own analytics workspace sourced from the same trusted data.
- Regulated data with multiple consumer groups. The hub restricts access to the engineering layer; each spoke gets only the aggregated, compliant views it's authorised to see.
- Multi-region deployment. One central hub with spokes for EMEA, APAC, and the Americas, each with localised reports and capacity while sharing the same underlying data.
When this breaks down
- Different domains need fundamentally different source systems or engineering logic, and one hub can't serve them all
- Spoke teams want to own their own data engineering as well as their analytics
- The platform team can't keep up with demand from all the spokes
- Cross-domain data products need tighter integration than shortcuts can cleanly support
When you hit these limits, Domain mesh topology is the natural next step.
Considerations
- Define the hub-to-spoke contract. Be explicit about which tables, which refresh cadence, and which quality guarantees the hub provides.
- Establish a change notification process. Schema changes affect every spoke, so build a communication channel with advance warning before breaking changes land.
- Standardise spoke setup. A template or checklist for new spokes keeps naming, folder structure, default roles, and monitoring consistent.
- Monitor the hub closely. It's a single point of failure; alert on pipeline failures, data quality issues, and capacity contention.
- Plan for spoke lifecycle. Have a process for decommissioning spokes, including cleaning up shortcuts and reclaiming capacity.